Issue #343
November 4, 2026
Announcements
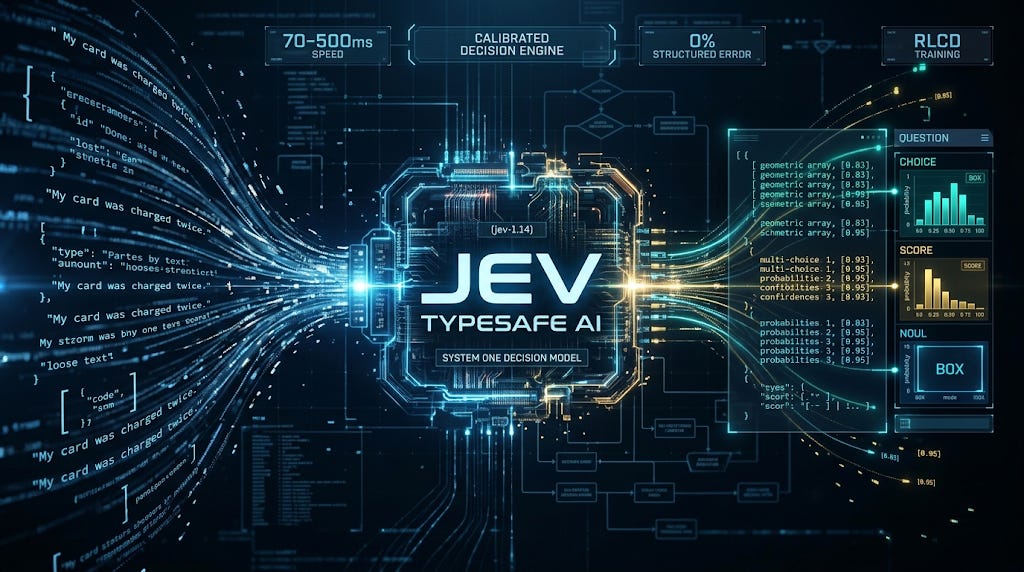
Do you really need a large language model for every AI task?
Jev takes a different approach: fast, inexpensive decision-making without generating text.
In my latest essay, Jev 101, I explain how it works and why it could change how we build production AI systems.
📖 https://data4sci.substack.com/p/jev-101
But how does it actually compare to Claude?
On November 18, I'm hosting a live, hands-on workshop where we'll put both models to the test, measuring accuracy, latency, and cost using real Python benchmarks.
Dear Reader,
Welcome to the Oct 21st edition of the Data Science Briefing.
Machines now work on machines. A new frontier lab wants AI to design the chips that train the next AI, and it aims to cut a two-to-three-year design cycle to weeks. A research post goes one layer down. GPT-6 Astra read and wrote raw neural network weights with no gradients and no training loop. It edited 0.016 percent of a small model’s weights, and math scores jumped from 7.9 to 48.1 percent. Mathematics feels the pressure hardest. OpenAI released more than 700 research papers on October 6, and a guest essay on a mathematics blog tells the field to stop mourning. The essay bets that choosing a worthwhile problem will soon matter more than producing the proof. People bring the machines their own lives. A panel of 73,852 Americans shared 3.4 million chatbot conversations, and health led all 28 subjects at 10.2 percent. Claude now offers lawyers a gallery of ready-made artifacts, from a cite checker that flags wrong quotes to a rent ledger reviewer. The model drafts the first pass, and a lawyer judges the result. Two data-series posts cover the basics. One learns image features from 6,000 unlabeled pictures. The other trains a tiny vision transformer to draw boxes, and it reaches a mean overlap of 0.815 against 0.309 for random boxes. The machines now draft the weights, the proofs, and the briefs. People still choose the problems worth drafting.
The research stack turns on one question. Compared with what? A study of 14.4 billion insurance claims from 244.7 million Americans compares people who tested positive with people who tested negative . Older designs drew controls from anyone without a known infection, and they even linked firearm injuries to the virus. The new design cuts the outcomes attributable to long COVID from 262 to 43 at one to four months, and from 369 to zero after a year. Symptoms past a year are real, the authors stress, but their cause is uncertain. A fairness framework asks whether an epidemic model reproduces who carries the burden, by age, race, or neighborhood. In a New York simulation, vaccines allocated by that measure cut deaths by 73.9 percent, against 68.2 for a split by group size. Industry leaves an environmental fingerprint, and one team reads it remotely. Air pollutants, night lights, and temperature predict steel plant output with an R² above 0.8. The machines need the same rigor. A new review makes the case for testing language models with the methods of experimental psychology, from biases to social skills. One such study explains why model prose tires readers. All nine frontier and near-frontier models used more rare word sequences than human writers, and fine-tuning under a length penalty pushed a model the same way. Good pairs build better representations. In an idealized setting, a new theorem shows that joint-embedding models trained on separate modalities learn one shared representation, up to a rotation. The condition is that each positive pair shows one scene twice. Next-token prediction pairs parts of one document instead. Good pairs reach the alignment of next-token prediction with 42 times fewer samples. A 109-million-parameter text model aligns with image encoders better than every language model tested, up to 72 billion parameters. The math under all of this fits in one free eight-chapter primer, from PCA through diffusion models, GANs, and energy-based models.
Our latest book recommendation is “Build with Claude Code” by T. Jo. In this week’s video, we have a look at 4 Failure Modes to Avoid in Context Engineering for AI Agents.
Data shows that the best way for a newsletter to grow is by word of mouth, so if you think one of your friends or colleagues would enjoy this newsletter, go ahead and forward this email to them. This will help us spread the word!
Semper discentes,
The D4S Team
"Build with Claude Code" by T. Jo: 9 projects, 408 pages, and you write none of the code. You describe each program in plain English. Claude Code does all of the typing. The author, Taeho Jo, studies early Alzheimer’s diagnosis with deep learning at the Indiana University School of Medicine. Packt published this English edition of his Korean original on August 31, 2026. Each project is bigger than the last one. They run from a single webpage to a database-backed shopping list on Vercel and Supabase.
Why should a data scientist read a beginner’s book? The answer is deployment. Most of us stall at the notebook stage of a project. A model on a laptop serves no users at all. This book ends with a live app and a real database behind it. The middle chapters teach habits worth stealing for model work. Chapter 5 drills hallucination checks on generated quiz content. CLAUDE.md files carry project rules from one session to the next. Custom commands turn repeated chores into one-line calls. Chapter 6 covers API keys, .env files, and .gitignore entries. Chapter 7 scopes an app with the 5W1H questions. Sub-agents then build it in product, frontend, backend, and QA roles. Chapter 8 adds MCP servers, Skills, plugins, GitHub, and Playwright to the kit.
Model builders face two problems with this book. It assumes no programming background from its readers. Part 1 spends four chapters on AI history, prompt basics, installation, and a to-do app. An ML engineer will clear that half in an hour. The bigger gap sits in the machine learning content itself. Only one project builds a model, a handwriting recognizer on the MNIST digits. No chapter title mentions notebooks, data pipelines, evaluation, or model serving. Claude Code ships new releases most weeks. The printed screenshots will age within months. So skim Part 1 in a single evening. Give Part 2 a full weekend at the keyboard. Data scientists rarely lack models, only the plumbing around them. Your last model still sits on your laptop. After Chapter 8, point Claude Code at it.
- 1. Recursive Self-Improvement via AI for Chip Design & Chip Design for AI [www.ricursive.com]
- 2. Sparks of Weight-Space Programming: LLMs can natively read & write neural network weights [rikiyat.github.io]
- 3. Mathematics has changed. Let’s act like it [terrytao.wordpress.com]
- 4. Learning representations without labels [stochastic.blog]
- 5. State of the Prompt: What People Ask AI [stateoftheprompt.net]
- 6. Object detection and vision transformers [stochastic.blog]
- 7. Introducing artifacts for legal work with Claude [claude.com]
- • A geospatial approach to measuring economic activity (Anton Yang, Jianwei Ai, Costas Arkolakis)
- • The Little Book of Generative AI Foundations: An Intuitive Mathematical Primer (Tianhua Chen)
- • Machine psychology for language models (Thilo Hagendorff, Ishita Dasgupta, Marcel Binz, Stephanie Chan, Andrew Lampinen, Jane X. Wang, Zeynep Akata, and Eric Schulz)
- • Fairness in infectious disease modeling (Yuhan Li, Nicolò Gozzi, Nicola Perra, Michele Tizzoni)
- • Proving and Improving the Platonic Representation Hypothesis with JEPAs (Randall Balestriero, Yann LeCun)
- • Revised estimates of types and duration of long COVID symptoms based on claims records from 245 million US patients (Hamed Nilforoshan, Julia Reisler, Erfan Jahanparast, Michael Moor, Steven N. Goodman, Stefan Wager, Jure Leskovec)
Context Engineering for AI Agents: 4 Failure Modes to Avoid

All our videos are also available in our
YouTube playlist.
Upcoming Events
Opportunities to learn from us.
Check out the
events page
for more details.
Enjoy the newsletter?
Forward it to a friend, or subscribe to get it straight to your inbox.
Subscribe Free